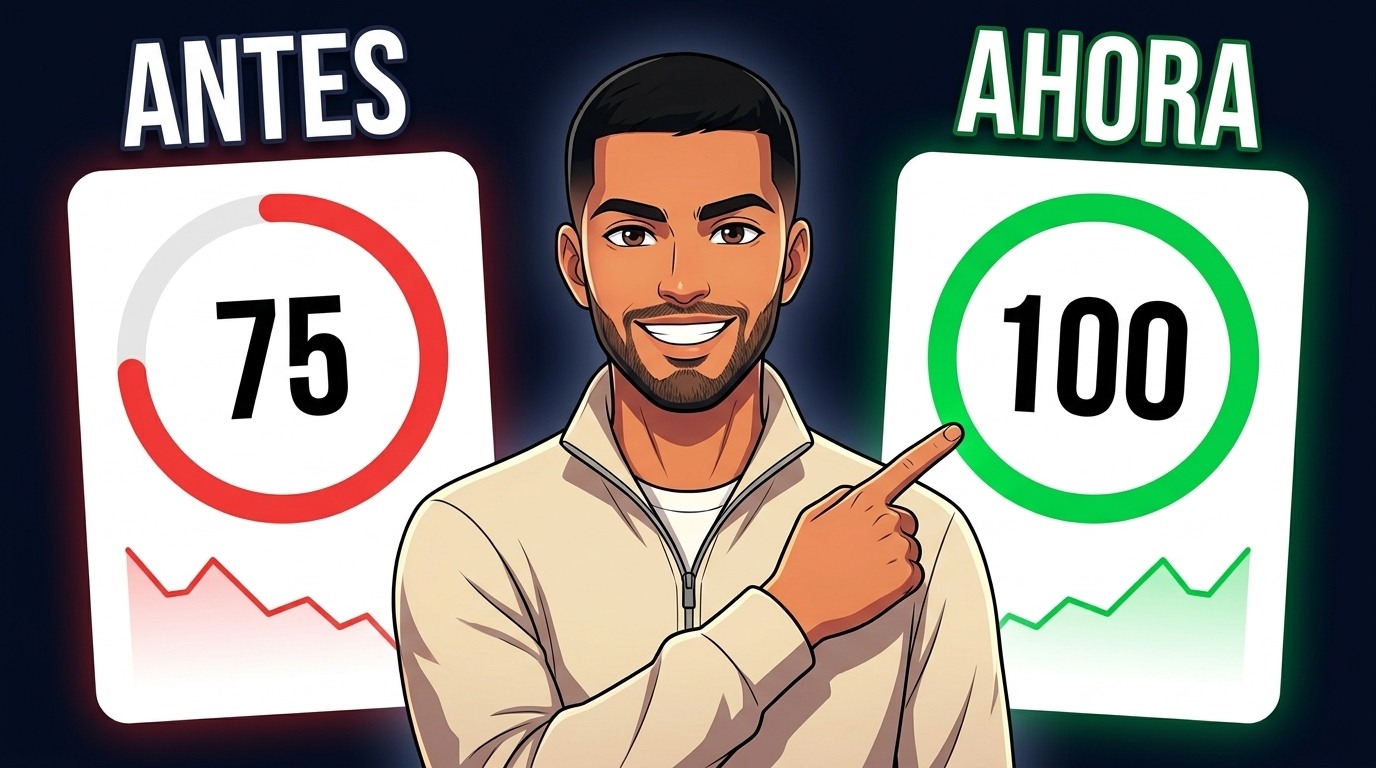
I searched Google for the service I sell, in my city, and did not show up. How I improved my website SEO step by step, with the scripts and metrics.
Free, in exchange for knowing who you are
Download it free
You get the whole thing at no cost. I only ask for your email so I can write later and ask how it went: if something did not work for you, I want to know. No spam.
One confirmation email and that is it. You can leave whenever you want.
What you will get
An audit gave my own site 75 out of 100. Worse: I searched Google for the exact service I sell, in my own city, and I did not show up. Not on the first page, not on the third.
I fixed every item, wrote down what worked and what cost me time, and packaged it into this skill. These are the final numbers, measured in production on the same site you are reading:
PageSpeed desktop: 92 → 100. Mobile: 77 → 91.
Layout shift (CLS): 0.137 → 0. Exactly zero, not rounded.
Fonts: 273 KB → 123 KB. 55% lighter.
Full load: 1,166 ms → 734 ms.
102 of 102 URLs with title and description within limits.
Open PageSpeed Insights, type chiragx.com, and check it yourself. I am not asking you to take my word for it.
My own site on September 10, 2026, measured by Google: 100 in performance and 100 in SEO. What took the page there is exactly what follows.
Before you start: install the skill
This is a Claude Code skill. Unzip the folder inside your skills directory:
~/.claude/skills/web-playbook-100/
On Windows that is C:\Users\YOUR-USER\.claude\skills\. It activates on its own when you ask to audit or improve a site's SEO.
Not using Claude Code? It still works. Everything is Markdown and the scripts run on their own from the terminal. Open SKILL.md and read it as the manual it is.
How to ask Claude so it does almost everything on its own
The skill activates when you talk about SEO, PageSpeed, Core Web Vitals, fonts, images or "why do I not show up on Google". To not depend on that, name it: use the web-playbook-100 skill. And give it these four things in the first sentence, because without them it has to ask:
The URL and the routes per language (/es/, /en/).
Where it is hosted and what you can touch. Cloudflare, WordPress, Shopify, a static HTML. And what you cannot touch.
What you want first: measure and propose, or apply. The healthy version is "measure, propose, change nothing until I approve", and then "apply changes 1 to 3 and measure again with the same command".
Access as environment variables, never pasted into the chat. A Cloudflare token with just the right permission, the PageSpeed API key. You create them and you revoke them when done.
One change, one measurement. Always ask for the before and the after with the same command, and for a list of what it could not verify. The prompt I start any site with:
Use the web-playbook-100 skill. My site is https://mydomain.com, routes /es/ and /en/,
hosted on [Cloudflare / WordPress / ...]. Run scripts/audit.sh with --sitemap and give me
the gaps ordered by impact according to the skill, with the command you used to verify
each one. Do not change anything yet.
Each step below carries the exact prompt, what Claude does on its own and what stays yours. At the end you get the full list of what nobody can do for you.
Step 1. Measure honestly, not the way you wish
Almost everyone skips this step, which is why they end up fixing the wrong thing. Before touching a line:
Open your site on your phone using mobile data, not wifi. Your office wifi lies to you. Your clients visit you on the street.
Run PageSpeed on mobile three times and take the middle value. A single measurement tells you nothing; it swings too much. Desktop almost always looks fine and is almost never where your visitors are.
Search Google for your service plus your city, in incognito. If you are not there, that is your real problem, not the score.
Count your services and count your pages. If you sell five things and have one page, that is your ceiling. Write that number down.
Save all four results in a file. At the end you measure the same four again, and that is how you know whether any of it worked.
The scripts/audit.sh script does the technical half for you: with --sitemap it checks status codes, redirects, canonicals, hreflang and metadata across every URL in your sitemap in one pass, and it also checks that you force HTTPS, which security headers you send and what your robots.txt says to each AI crawler. And scripts/psi.js runs PageSpeed three times, takes the median and lists what is requested before the LCP.
Desktop always looks good. Measure on the phone, which is where people visit you.
Ask for it like this:
Measure https://mydomain.com/es/ with scripts/psi.js three times on mobile (PSI_KEY is in
the environment), run blocks 1 to 3 of scripts/browser-audit.js on the page and save
everything in baseline.md. Change nothing.
What it does on its own: PageSpeed with a median, the list of what loads before the LCP, CLS and LCP in a real browser and the curl battery. What stays yours: get the free PageSpeed API key (five minutes, with your Google account), open the site on your phone on mobile data, search your service plus your city in incognito from your city, and count your services.
Step 2. One page per service, not a list on the home
This moved the needle more than anything else, and none of it is technical.
If you sell five services and they live as five paragraphs inside your home page, Google has one page to rank for five different searches. It will lose all five. Each service needs its own URL, its own title, its own description and real content of its own.
In my case I went from a home page with a services section to twelve pages (six services in two languages), each with:
A title using the words people actually type, not the ones we use in the industry.
A concrete problem at the top, before talking about me.
Real frequently asked questions, the ones I get on calls.
Structured data for Service and FAQPage.
Cross links between related services, and back to the index.
The skill covers this in references/arquitectura.md, including how to decide what deserves its own page. Short rule: if someone could search for it by name, it deserves a page.
Ask for it like this:
These are my services: [list]. Using references/arquitectura.md tell me which ones deserve
their own URL, propose a slug in Spanish and English, a title of up to 60 characters and a
description of up to 158 for each, and the section structure. Write only once I give you
prices, real client questions and cases.
What it does on its own: decide what deserves a page, propose slugs, metadata and structure, write, and link the silos in both directions if it has your code. What stays yours: the facts (prices, ranges, the questions people really ask you, cases with numbers), approving every text and, on a visual builder, creating the pages by hand.
Step 3. Technical SEO: let Google read you without guessing
This is where most sites lose points to invisible things. The order that works:
Structured data. Mark who you are (Person or Organization), what you sell (Service), your questions (FAQPage) and the navigation path (BreadcrumbList). Validate every page in the Rich Results Test.
A canonical on every page. One official version of each URL.
Hreflang if you have more than one language. Reciprocal: if the Spanish one points to the English one, the English one has to point back. If one fails, both fail.
A generated sitemap with a real lastmod. A hand-written sitemap goes stale in two weeks.
Titles and descriptions within limits. Title up to 60 characters, description up to 158. Past that, Google truncates them and you lose the message.
Once that is in place, verify the site in Google Search Console, submit the sitemap and request indexing for the new pages. Also register on Bing Webmaster Tools: it takes half an hour and it feeds a good share of what AI search engines answer with.
Search Console has a learning curve, and some decisions depend on how your site is built. I am listing it as a step because explaining it properly is a conversation, not a paragraph. Write me and we go through your case.
And one almost nobody checks: force HTTPS
Having a certificate is not the same as forcing it. You can have the padlock and still serve the entire page unencrypted at http://yourdomain.com, with a 200 response and no redirect anywhere. It happens more than you would think, and you can check it in a second:
If that chain never jumps to https://, you have three problems at once. One: your contact form travels unencrypted. Two: old links pointing at http://www. count as a different URL, so the authority they send you gets split instead of added up. And three, the one nobody connects: every extra redirect costs mobile load time. In a real measurement I ran, the redirect chain was eating 0.61 seconds of rendering.
On Cloudflare it is one switch: SSL/TLS → Edge Certificates → Always Use HTTPS. If you are not on Cloudflare, it is a 301 redirect rule on your server.
While you are there, check whether you send any security headers. Odds are you send none. A _headers file (or your host's equivalent) covers the sensible minimum:
A warning about HSTS: it forces browsers to remember for months that your site is HTTPS only. It is good, but if something breaks you cannot undo it quickly, because the instruction already lives in every visitor's browser. Turn it on once the rest is stable, not on day one.
Ask for it like this:
Fix canonical, reciprocal hreflang with x-default, a sitemap with real lastmod, and the
titles and descriptions outside the limits in [my code / my template]. Generate the JSON-LD
per template and check that it parses. Check forced HTTPS and headers. Before and after
with scripts/audit.sh --sitemap.
What it does on its own: everything that lives in the code or the template, plus the check from the outside. With a Cloudflare token, also the HTTPS switch and the headers. What stays yours: verifying the site in Search Console and Bing Webmaster Tools, submitting the sitemap, requesting indexing URL by URL (Google gives a small daily quota), deciding on HSTS and, without a token, flipping the switches in your hosting panel.
Step 4. Performance: what actually moves the number
This is the area with the most myth per square meter. What actually worked, in order of impact:
Fonts
Google Fonts costs you a connection to another domain before a single letter can paint. Download them and serve them yourself. Two warnings that cost me time:
Google serves a single variable file per family. If you download "regular", "medium" and "bold" separately, you are downloading the same file three times. Deduplicate by hash and declare weight ranges.
Use font-display: optional on your body font. With swap the text repaints, and that is where a good chunk of your layout shift is born. swap is only acceptable once you have tuned the fallback with measured metrics (block 5 of browser-audit.js computes them): then the text repaints but nothing moves.
scripts/selfhost-fonts.js handles the download and the deduplication for you.
Images
Convert to AVIF and serve with <picture>, keeping the original as a fallback. My home page went from 1,013 KB to 533 KB with no visible difference.
Declare width and height on every image. Without them the browser cannot know how much space to reserve, and content jumps.
If you have a global img{max-width:100%} rule, it must include height:auto. Without it your images get squashed. This bug lived on my site for weeks and I only caught it in a screen recording.
Layout shift
Getting to zero is about reserving space: dimensions on images, heights on anything that loads late, and nothing that moves when the font arrives. scripts/browser-audit.js measures shift, largest paint and real contrast in an actual browser, which is different from what a lab reports.
Serve the image at the size it is displayed, not just in the right format
Converting to AVIF is not enough. A 1000px-wide file dropped into a 340px slot still ships three times the pixels anyone sees. PageSpeed reports it as Improve image delivery and tells you exactly how much is wasted.
The rule is simple: look at the real on-screen width, multiply by two (for high-density screens) and generate that variant. A 340px slot means a 700px file. On my own site that was a single image wasting 23 KiB.
And one that costs you: if you change what an image shows, change its filename. Images are usually served with a thirty-day cache. Rewrite the same file and everyone who already saw it keeps seeing the old one for a month, while you tick it off as fixed.
CSS backgrounds are never lazy, and that costs you mobile LCP
loading="lazy" only exists for <img>. Any background-image, inline or in CSS, is requested the moment the element exists, wherever it sits. On my home page that was twenty card backgrounds (events, covers, YouTube thumbnails) several screens below the fold: 642 KB of images requested before LCP, competing on slow 4G with the hero text. Result: the main paragraph took 3.5 s to paint with its HTML ready since half a second in.
The first thing I tried, content-visibility: auto on the far sections, does not prevent it: Chrome stops painting the section but keeps downloading its backgrounds. I checked it in the trace. Rule it out for this.
What works is not declaring the background until it is needed: the declaration lives in a data-bg attribute and a ten-line script moves it into style when the element approaches the viewport. With a scroll-based checker, like the one used for reveal animations, so it does not depend on IntersectionObserver running:
<div class="event-img" data-bg="background-image:url('/images/event.jpg')"></div>

(function(){var els=[].slice.call(document.querySelectorAll('[data-bg]'));var t=null;
function apply(el){el.style.cssText+=';'+el.getAttribute('data-bg');el.removeAttribute('data-bg');}
function check(){t=null;var h=window.innerHeight+600;
  els=els.filter(function(el){var r=el.getBoundingClientRect();
    if(r.bottom>-600&&r.top<h){apply(el);return false;}return true;});}
function onS(){if(!t)t=setTimeout(check,80);}
window.addEventListener('scroll',onS,{passive:true});window.addEventListener('resize',onS);
window.addEventListener('load',check);check();})();
If your server renders the cards, the change goes in the template and the script in the shared footer, so every page has it. With that, bytes requested before LCP dropped from 958 KB to 434 KB. On Google's PageSpeed: mobile from 88 to 91 with LCP from 3.5 s to 3.2 s and CLS 0; desktop 99 with LCP 0.7 s. (Local Lighthouse gives 95 and 2.4 s; Google simulates a slower network, and that is the number that counts.)
The way to find this is not guessing: in the Lighthouse JSON, list the requests that started before LCP and sort them by size. That shows, on one screen, what is stealing bandwidth from the element that matters.
Contrast can fail in one theme and pass in the other
If your site has light and dark modes you have two palettes, and the audit measures one: whichever you serve by default. The same colour gave me 6.16 in dark and 4.47 in light. The minimum for small text is 4.5. Three hundredths short and it is flagged red.
Check both themes before calling accessibility done: in the browser, forcing the scheme and measuring the computed colour against its real background.
A warning on method: do not trust your own automated sweep. If text sits on an image or a gradient, computing contrast against the container's background colour produces invented numbers. A script like that handed me thirty-one failures, of which one was real. Lighthouse's own list is the reliable source here; your script confirms it, it does not replace it.
Ask for it like this:
Fonts: run scripts/selfhost-fonts.js with my Google Fonts URL, replace the external tags
with local @font-face rules using weight ranges and compute the fallbacks with block 5 of
browser-audit.js. Images: scripts/to-avif.sh over /images, picture with fallback, width and
height, and data-bg for backgrounds below the first fold. One change per deploy, and CLS
and LCP in the browser after each one.
What it does on its own: fonts, fallbacks with measured metrics, AVIF, dimensions, lazy backgrounds, contrast from the tokens and the measurement. What stays yours: approving every deploy and looking at the site on your phone after each one, because the number cannot see if something looks wrong. And the CDN settings if you gave no token.
Step 5. Entity: let Google know you exist as a person or company
Almost nobody does this, and it is what separates "one more website" from "the reference on this topic in your country".
Google does not only index pages, it maintains a graph of entities: people, companies, places and how they relate. If you are not an entity to Google, you compete on words alone. If you are, you compete on being who you are.
The steps, in order:
Mark Person or Organization on your site with a stable @id, and reference that same @id from every page.
Link with sameAs to your real profiles: LinkedIn, GitHub, YouTube, X, your company listing.
Make all those profiles say the same thing. Same description, same name, same link. If your LinkedIn says one thing and your site another, you are sending signals that contradict each other.
If you have press coverage, talks, or existing entities that mention you, create your record on Wikidata and connect it to your companies.
Wikidata has notability rules and your entry can be deleted if you do it wrong, so do not take it lightly. It is covered in references/entidad.md, but if you are doing this for your business, talk to me first and I will tell you whether you qualify and how to approach it.
To Google you are a node connected to others, or you are nobody. That is the entity.
Ask for it like this:
Generate the Person or Organization block with a stable @id and sameAs pointing to these
profiles: [list]. Put it in every template referenced by @id. Write a description of up to
150 characters that works the same on Instagram, X, LinkedIn, YouTube and Facebook. Look for
independent sources about me and tell me whether I qualify for Wikidata and with which references.
What it does on its own: the schema, the description and the draft of the item with its sources. What stays yours: editing each social profile with your session, creating the Wikidata item with your account and answering if it gets challenged, suggesting the change on the Google panel and claiming your business profile.
Step 6. Content and measurement: so this does not die in a month
A site at 100 that publishes nothing drifts back down. You need two things.
Somewhere to publish without touching code. I built my own CMS on Cloudflare because I wanted control over the HTML that comes out, but anything works as long as you actually publish. What matters is that posting an article takes fifteen minutes, not an afternoon: if it is painful, you will not do it. The setup is in references/stack.md and references/cms-y-contenido.md.
Knowing where people come from. Measure first touch, not last: if someone found you through Google in March and messaged you on WhatsApp in May, that was Google, not WhatsApp. Store the source in the browser on the first visit and send it with the form. Without this you are guessing which channel brings you clients.
Ask for it like this:
Set up first-touch capture (utm_source, utm_medium, utm_campaign, referrer, landing page
and date) stored in the browser and sent with the form. Generate my UTM links for
[channels]. Propose an article calendar: two purchase-intent pieces for every news piece,
with the search title of each one.
What it does on its own: the attribution code, the UTM links, the calendar and the drafts. What stays yours: connecting the CRM or the inbox where the leads land, actually using the UTM links on each channel, publishing on a rhythm and approving every article. The experience is yours; nobody invents it for you.
Step 7. Links: why "I have 112 backlinks" can mean zero
This is the step most people skip, and the only one where you cannot cheat.
Here is what will happen: you run an audit, it tells you that you have a hundred-odd inbound links from thirty domains, and you feel good. Then you look at the list and find domains like .sbs, .cfd, .icu, .party, .monster, with titles like "seo domain research", "Domain Report" or "URL Shared", almost all hosted in Finland or France.
Those are not links. They are automated junk. They generate themselves every time someone runs your domain through an analysis tool: the tool publishes a page with the result, and that page links to you. Running audits manufactures them. They do not hurt you, because search engines ignore them, but they add nothing either, and they give you a false sense that you already have links.
How to tell a good one from a bad one, without a paid tool:
Did a human write that page? If the title is "Domain Report" or a number, no.
Does the anchor text say anything? "yoursite.com" repeated a hundred times is automated. "Founder profile" was written by a person.
Does it make sense for that site to mention you? An event organiser where you spoke, yes. An Estonian URL shortener, no.
Now what actually works, easiest first:
Your own properties. If you run several companies, brands or projects with websites, check which ones link back. In my case, out of five of my own companies, three did not link to me: my site was sending them authority and getting nothing back. It is the easiest link there is and it costs nothing.
Sites where you already appeared. Events where you spoke, podcasts, clients with case pages, associations. Many already mention you without linking, or link badly. One message and it is done.
Check how the ones who do link are linking. Almost nobody does this and it is money on the floor. One organiser had me as http://www.mydomain.com: unencrypted, with www, and two redirects before landing. The link existed, but it arrived at the wrong URL. Asking them to point it at the right one is a two-line message.
Partners and allies. If you already feature them on your site, asking for reciprocity is fair.
What I do not recommend: buying links, mass link exchanges, or paying for "500 guaranteed backlinks". That builds exactly the profile I just described as junk, and you paid for it.
One note on expectations: this is slow and one afternoon will not fix it. It is the only step in this guide that depends on other people, which is why it is the one most people abandon.
Three links written by a person outweigh a hundred from automated domains.
Ask for it like this:
Here is the backlink list from my audit: [pasted or CSV]. Split it into real and automated
using the skill's criteria. Then run scripts/enlaces.sh with my domain, my brand and these
URLs where I appear: [list]. Write the two-line message for each correction.
What it does on its own: splitting the list, checking how each page links to you (unencrypted, with www, with hops, with nofollow) and who mentions you without a link, writing the messages and fixing the links on your own properties if it has access. What stays yours: sending each message, asking partners for reciprocity and waiting. It is the only step that depends on other people.
Step 8. Make sure the AIs can read you too
More and more people do not search: they ask. ChatGPT, Claude, Gemini, or the summary Google puts on top. If your site is tuned for the classic search engine but the models cannot read you, you disappear from half the queries without noticing.
The good news is you already did most of the work in steps 3 and 5. What is left is small:
Your content must be in the HTML, not painted with JavaScript. This is the big one. Many AI crawlers do not run JS: they read what comes in the response and that is it. Check it with curl -sL https://yourdomain.com/ | grep "a sentence from your page". If it does not show up, your page is blank as far as those models are concerned.
Do not block AI crawlers. Check your robots.txt. If you use Cloudflare, look at whether automatic AI bot blocking is on: it ships enabled on some accounts and decides for you.
Add an llms.txt at the root. It is a text file that tells the model what your site is and which pages matter. The standard is young, it takes twenty minutes, and there is still no reason not to have one.
Identity schema. Same Person or Organization from step 5. For a model, that block is the cleanest way to know who you are without guessing.
This is what audits are starting to report as GEO (Generative Engine Optimization). It is new enough that almost nobody has it, which is exactly why it is the cheapest place to stand out right now.
Many AI crawlers do not run JavaScript: what is not in the HTML does not exist for them.
Ask for it like this:
Check that the main content is in the HTML without JavaScript on my main pages, review
robots.txt for GPTBot, OAI-SearchBot, ClaudeBot, PerplexityBot and Google-Extended, and
write an llms.txt with my important pages. Tell me what I have to switch off in Cloudflare.
What it does on its own: the check, the robots.txt, the llms.txt and, with a token, both Cloudflare controls. What stays yours: without a token, switching off the AI bot block under Security and "Managed robots.txt" under AI Crawl Control. And deciding whether you want the AIs to read you. The answer is usually yes.
The mistakes that will cost you time
The skill documents twenty-four real mistakes in references/errores.md, each with what it cost. These six are the ones I see most:
Optimizing desktop and celebrating. Desktop always looks good. Your traffic is mobile.
Chasing the score instead of the business. A 100 that does not show up when people search your service is worth nothing. Measure both.
Trusting the lab. Tools simulate. Open a real browser and measure there before calling anything done.
Thinking the padlock is enough. Having a certificate and forcing HTTPS are different things. Check it with curl, not by looking at the browser bar.
Counting backlinks without looking at them. A hundred links from automated domains are worth less than three from sites that genuinely mention you.
Changing ten things at once. If it improves, you do not know which one did it. If it gets worse, same problem. One change, one measurement.
SEO audit flyer: your site failed, shall we review it?
What you have to do yourself, no way around it
With the skill and a tightly scoped token, Claude does most of the work and verifies it. This part nobody can do for you, and it is exactly where almost everyone gets stuck:
Accounts and verifications. Search Console, Bing Webmaster Tools, the PageSpeed API key, your Google Business Profile. They are verified with your DNS or your account.
Requesting indexing on Google. Search Console, URL inspection, "Request indexing", one by one and with a daily quota. Bing accepts hundreds a day, and IndexNow can be automated.
Panel switches. Forcing HTTPS, HSTS, the two AI crawler blocks in Cloudflare, image transformations. With a token holding just the right permission Claude changes them; without one, you flip them.
Secrets. You create tokens and keys with the minimum permission, pass them as environment variables and revoke them when done. Never in the chat.
The facts of the business. Prices, ranges, real client questions, case numbers. Claude cannot invent them and must not.
Approving every text and every deploy. One change, one measurement, and the site on your phone afterwards.
Your phone and your city. Opening the site on mobile data and searching your service plus your city in incognito. No tool sees what you see from there.
Profiles and Wikidata. Editing each network with your session, creating the item with your account, suggesting changes on the Google panel.
Links. Sending the messages to organizers, partners and media. The only item on the list that depends on other people.
Rhythm. Publishing. A site at 100 that publishes nothing drops again.
How you know you got there
Go back to the four numbers from step 1 and compare. You are there when:
Mobile is above 85, measured three times.
Layout shift is at zero.
You show up when searching your service plus your city, in incognito.
Every service you sell has its own indexed URL.
Your domain forces HTTPS and no URL is left serving unencrypted.
The sites linking to you point at the right URL, and at least one was written by a person.
If everything lands except showing up in the search, what is missing is usually time, entity (step 5) and links (step 7). They are the two slow steps and the ones that pay the most.
Getting Google to recognize you as an entity
Google finding your pages is one thing. Google knowing who you are is another, and that's what earns you a knowledge panel next to the results and lets AI models talk about you without making things up. To Google, you're an entity when your name, photo, companies and profiles add up to a single, well-connected node in its knowledge graph.
Here's what I did on chiragx.com, in the order I'd do it again, including what worked and what cost me.
1. Start with a page you own: About/Press
Everything starts on your own domain, because it's the one thing nobody can delete. My About Chiragx page has a quick-facts box, a short bio, my official profiles, my companies and a list of talks, press and media, each one linked to its source. It doubles as my press kit and it's the source for everything else. Link to it from the footer of every page.
2. One Person for the whole site
Under the hood, that page is a ProfilePage whose mainEntity is my Person, with an @id that never changes: https://chiragx.com/#chiragx. The same @id shows up on the home page and on my link-in-bio page, and the site and my service point to it as publisher and founder. Google sees one person, not five lookalikes.
Two details almost nobody gets right:
Consistent sameAs. The same list of real profiles, Wikidata included, on every page that carries the full block. Eight profiles on one page and five on another means you're showing Google two versions of yourself. The safest setup: the full block on the home page and the About page, identical, and just the @id everywhere else.
image as an ImageObject. Not a bare URL: an object with your portrait's URL and a caption with your name. That's the photo you want Google to associate with you.
People will tell you not to create your own item because it gets deleted as a conflict of interest. I was told that too, and I believed it for months. In July 2026 I created mine, and it's still up: Q140753224. What made the difference:
Notability backed by references. Wikidata accepts an item when it can be described with serious, public references, or when other items need it. My key statements (occupation, residence, photo) each cite an external source: conference agendas, press coverage, interviews. Your own site doesn't count as proof.
No sales pitch. A short, factual description. The deletion risk is real: an item with no sources that reads like self-promotion ends up on the requests for deletion page.
The properties that matter. Instance of: human. Occupation, residence, official website, your username on each social network and, if you have a freely licensed photo on Wikimedia Commons, an image.
Connected to your companies. Each of my companies has its own item with country, headquarters, website and a "founded by" statement pointing to me. That link is what turns a standalone item into part of the graph.
Both directions. The item points to my site, and my site's sameAs points back to the item.
Google already shows a knowledge panel when you search for "chiragx", and its subtitle matches the occupation I declared on Wikidata. That's why the item is worth writing carefully before you ask Google for anything.
4. A public name that stays put
Pick the name people actually search for and leave it alone. Mine is "Chiragx": it's unique and it's what people type. In the schema it goes in name, with my legal name and its variants in alternateName. Wikidata works the other way around: the label is my legal name and "Chiragx" is an alias.
At one point I considered switching everything to my first and last name to "tidy up" the entity. I dropped the idea: the panel was already showing up for "chiragx", and I wasn't going to break something that works to chase something else. The variants still do their job as aliases.
5. Profiles that match, character for character
LinkedIn, Instagram, YouTube, Facebook and X need to agree on three things: your name, the link to your site and the names of your companies. Your bio can change language from one network to the next; your name can't. If one profile says "My Company" and another says "MyCompany", Google sees two different companies. And if you change a username, update your sameAs, your llms.txt and Wikidata the same day.
6. Claim your panel and use "Suggest edits"
Line everything up first, then ask. Google checks what you suggest against what it finds elsewhere, and if your profiles contradict each other, the suggestion goes nowhere.
Claim it. Search for your name, open the panel and choose to claim it. The route that works is signing in with the Google account that verified your domain in Search Console (or the one that owns your official YouTube channel). Manual verification with documents rarely gets an answer.
Suggest edits. Once you're verified, you can suggest changes to the photo, the name and the profiles. The description isn't editable there: it comes from Wikidata.
7. The photo rule (learned from the wrong photo)
One day Google put a photo of a business partner on stage in my knowledge panel. That wasn't Google's fault, it was mine: every photo in my event galleries had a generic alt like "Event name | Chiragx", whether I was in it or not, and the gallery's JSON-LD said it was about me. Google believed my site.
What I do now:
My name goes in the alt text, caption and schema only for photos I'm actually in. When other people are in the shot, I say where I am: "Chiragx on the left, gray blazer".
If I'm not in it, I describe who is. If the photo could be confusing, I add "(not Chiragx)".
No generic alts with the brand tacked on. "Event | Brand" across forty photos teaches Google that all forty are you.
Galleries are marked up as part of the event, not as being about me, and their JSON-LD and social image only use photos I'm in.
Folders with photos of other people get an X-Robots-Tag: noindex header: they stay on the site, but Google Images won't use them.
I never identify anyone from a thumbnail. I open the full-size photo and compare it with my portrait.
One warning: after the fix, my panel was left with no photo at all. Google won't add one on request; it has to come back on its own. Once it does, the panel's verified owner can propose a different one by pasting the image's direct URL.
8. Let the AIs in: robots.txt and llms.txt
More and more people ask an AI model instead of searching. I want to be cited, so my robots.txt allows everything and also names each AI crawler explicitly:
Two traps. First, a bot with its own group ignores the general one, so anything you block there (your admin panel, for example) has to be repeated in each group. Second, if you're on Cloudflare, the file being served may not be yours. The "Managed robots.txt" option in AI Crawl Control was injecting a block that kept training bots away and contradicted my own file. I turned it off and unblocked every crawler. Check with curl https://yourdomain.com/robots.txt: if you see a block you didn't write, it's back on.
Then publish an llms.txt at the root: a Markdown summary of who you are, what you do, your key pages, your profiles and your Wikidata item. It's a proposal, not a standard, so don't expect it to move Google; but it takes ten minutes and some assistants read it. In my case, Cloudflare's data already showed OpenAI and Apple fetching my articles.
9. Request indexing, then be patient
None of this counts until Google crawls your site again. After every change to schema, alt text or photos, go to Search Console, inspect the URL and request indexing, starting with the home page and the About page. To pull an image from the results quickly, use Removals. And list the photos you're actually in on your sitemap, so Google has something to replace the wrong one with.
If the title Google shows doesn't match the one in your code, don't edit it again: Google simply hasn't recrawled yet. You don't request a knowledge panel, you earn it. You can do everything right and still wait weeks or months. What you do control is that when Google looks, everything tells the same story.
Ask Claude like this:
Use the web-playbook-100 skill, references/entidad.md. My site is https://mydomain.com. Review my About page and the Person JSON-LD in all my templates: one @id, the same sameAs list wherever the full block appears, and image as an ImageObject. Check the alt text in my galleries against the photo rule and tell me which ones to fix. Check my robots.txt and llms.txt. Look for independent sources about me and tell me whether I qualify for Wikidata, with which references and which properties. Don't change anything until I approve.
What it does on its own: the schema, the alt text review, robots.txt, llms.txt and a draft Wikidata item with its sources. What's on you: creating the item with your own account and answering if editors push back, aligning your profiles while signed in, claiming the panel with the account that owns your domain, and requesting indexing in Search Console.
Frequently asked questions
Which SEO metrics should I watch to improve?
A few, and always the same ones. In Search Console: clicks, impressions, CTR and average position, by query and by page. In PageSpeed, on mobile and using the median of three runs: LCP, CLS and INP. And the test that does not lie: search for your service plus your city in an incognito window. If a metric does not tell you what to fix, do not check it every day.
Can you improve rankings without backlinks?
Up to a point, yes. Technical fixes, performance, one page per service and the entity can take you from not showing up to ranking for your name and for your service in your city. For competitive searches, links that a person actually wrote still matter. The easiest ones are your own properties and the sites where you have already appeared (step 7).
How long until it shows?
Technical and performance fixes show in PageSpeed the same day. In Google, new titles and new pages usually show within days or weeks, depending on how often your site gets crawled. The entity and links are the slowest part: think months, not days.
What is crawl budget, and does it affect me?
It is how many pages of your site Google crawls in a given time. On a site with tens or hundreds of pages it is almost never the problem. What does help is a clean sitemap, with no redirects or duplicate URLs, and every page answering 200 with its canonical.
Do I need to know how to code to do this?
No. The skill does almost everything with Claude Code. What is on you: the accounts, the keys, and approving each change before it goes live.
Free, in exchange for knowing who you are
Download it free
You get the whole thing at no cost. I only ask for your email so I can write later and ask how it went: if something did not work for you, I want to know. No spam.
One confirmation email and that is it. You can leave whenever you want.
Stuck on a step?
Write me and we look at it
The resource takes you from zero to a hundred on its own, but some steps land better in a conversation. If you got that far and something is off, send me your site and I will tell you what is going on.